Building a USAspending MCP Server: What We Built, and Why
Ask a coding agent “what contracts has DEVTECH Systems won in the last year?” and it does one of three things: confabulates an answer, scrapes a webpage, or gives up. All three are worse than the data, which already exists. The US federal government publishes essentially all of its contract and spending data through a free REST API — USAspending.gov — no account, no API key. The missing piece is a bridge between that API and the agent. That bridge has a name now: MCP (Model Context Protocol).
In this article we walk through the MCP server we built on top of USAspending: 14 tools, one 700-line Python file, one dependency, no key required. We cover what MCP actually is (and is not), the two design decisions that mattered, the war story that took most of the effort — which was not the MCP part — and a straight answer to the question every skeptical reader is forming right now: “the AI can read the API docs. What does your MCP actually buy?”
Five words, five things
The terminology around this is noisier than the technology, so here is the vocabulary as we use it, one line each:
- API — not the data itself, but the way to get it: a set of HTTP endpoints and the rules for requesting and receiving it. The spending records live in the government’s databases; the API is the door. Nothing AI about it, and USAspending’s API has existed for years.
- Model — the reasoning engine (GPT, Claude, Qwen, whatever).
- Agent — a model plus a loop plus tools: it decides what to do, calls a function, reads the result, and repeats until it has an answer.
- Tool — one callable function the agent can invoke. “Search awards by recipient” is a tool.
- MCP — a standard format for packaging and discovering tools, so any agent client can use them without bespoke integration code.
The analogy we find honest is USB-C. MCP standardizes the connector, not the device. A well-built device works in any port; a badly-built one — wrong tool design, no error handling, giant result payloads — is still badly-built in every port. Nothing about MCP makes the underlying work good. It just means you do the underlying work once.
When an MCP server is the right tool
MCP earns its place when:
- the data source is a stable, documented API (not a PDF, not a login-walled portal),
- the queries repeat — the same shapes of question over and over,
- more than one client should use it: your own different agent harnesses, teammates, clients.
It does not make sense when: you need one lookup (a script or a prompt with the API docs is enough), the data has no stable API, or the “analysis” is really a bespoke pipeline that happens to start with a data fetch. We will come back to the first point, because it is the strongest objection to this whole project.
What we built
The server is a single file with 14 tools: search_awards, search_transactions, award_counts, spending_by_category, spending_over_time, recipient_profile, autocomplete, agency_overview, agency_subagencies, subawards, reference, start_award_download, check_download_status, and opportunity_dossier (a one-call market dossier that fans out to four of the others). It runs on stdio transport and needs no credentials.
Two design decisions did most of the work.
Tool design is product design. Our first version had 16 tools, including five separate autocomplete endpoints (NAICS, PSC, location, recipient, awarding agency). We merged them into one autocomplete tool with a kind parameter:
@mcp.tool()
async def autocomplete(query: str, kind: str = "naics", limit: int = 10) -> dict:
    """Autocomplete lookups. kind: naics | psc | location | recipient | awarding_agency.
    recipient: company name -> legal-name candidates (+ UEI/DUNS where known).
    ..."""
Why: an agent picks a tool by reading its docstring. Sixteen similarly-named tools means more of the agent’s context spent on tool schemas and a real chance it picks the wrong one. Fourteen sharp tools with long docstrings means the right call is usually obvious. The same logic applied to result size — search_awards has a fields projection parameter with a sensible slim default, because a 100-row × 40-field payload is the fastest way to burn out an agent’s context window.
One file, zero local imports, one dependency. The file imports only the framework (fastmcp) and Python’s stdlib for HTTP. No shared modules, no local package, no environment you must replicate. That was a hard requirement, not a nicety: if any machine with any Python can run the file, then any harness on any of our machines can use it, and a client can run it in five minutes without us on a call.
The 14 tools, by job
The tools group into five jobs. An agent typically works its way down the list: resolve the vocabulary, search, size, then dig.
Getting exact terms first. Two tools turn fuzzy language into the exact codes the search tools require.
autocomplete— a fuzzy term to candidates: “management consulting” → NAICS 541611, “DEVTECH” → five company-name candidates, “GSA” → numeric agency code. One tool, fivekindvalues (naics, psc, location, recipient, awarding_agency). The recipient result is candidates only — near-identical company names across states are common, so the agent must disambiguate before relying on a match.reference— the static tables: the full NAICS tree with award counts, all top-tier agencies with their numeric codes, valid award types, glossary. The dictionary the agent consults to make sure it is asking with the right vocabulary.
Searching the awards.
search_awards— individual prime awards (contracts by default; grants, IDVs, loans viaaward_type_codes), filtered by NAICS, keywords, agency, dates or fiscal years, dollar range, business type (Small Business, 8(a), HUBZone), or recipient name. Two caveats are built into the docstring: Action Date comes back null on this endpoint (if you care about when, use the next tool), and a 200 with zero rows can mean “no match” or “your filter combination was silently dropped.”search_transactions— the same filters, but one row per action (each contract, modification, and task order) with real dates. This is the tool for “most recent N.” A row withMod == "0"is a new contract; everything else is activity on an older award.award_counts— just a count of matching awards. Cheap and fast, and the docstring tells the agent to call it first to size a search — it is also the way to tell “genuinely no matches” apart from “my filter was silently dropped.”
Sizing a market.
spending_by_category— obligated dollars grouped by who: recipients, awarding sub-agencies, NAICS, states, funding agencies, and more, sorted by amount. This is the “who are the top players” tool.spending_over_time— a trend line of obligated dollars by fiscal year, quarter, or month. This is the “is this market growing or shrinking” tool.
Deep dives.
recipient_profile— one company’s profile: alternate names, UEI, DUNS, parent, business types, location, lifetime totals. Takes the hash id from search results — not the UEI, which the docstring flags because it is an easy mistake.agency_overviewandagency_subagencies— a top-tier agency’s totals for a fiscal year, then the same for each sub-office.subawards— the subcontract layer: who does work under a given prime, or which subcontracts a company has received (a teaming signal).
Bulk export, and the composite.
start_award_download+check_download_status— a pair: kick off an asynchronous CSV-zip export of everything matching a filter set (useful when the search is large or you need fields the live API returns as null), then poll until it is ready.opportunity_dossier— the entry point for “evaluate this opportunity.” Given target NAICS, it fans out in parallel to the other tools and returns in one call: market size, fiscal-year trend, top buyers, top winners with UEIs, top states, and the last twelve months of awards for incumbent detection — plus explicit caveats (amounts are action obligations and can exceed base value on multi-year awards; “winners” is history, not a win-probability signal).
A demonstration: a real session
The GIF below is not a walkthrough. It is a recording of a live Hermes session from October 5, 2026, running against the server in this environment — the .cast file, not a re-render, and the numbers are what the API returned that morning, not staged output. Three questions, at original speed:
Question 1: “use usaspending mcp to find how much did DoD award to contractors in FY2025.” Two tool calls, visible in the recording with their durations — spending by category (1.2s) for the dollar total, then award counts (1.1s) for context. The answer:
- Total obligated (contracts, all prime awards, DoD as awarding agency): $491,782,181,916.41
- Matching records: 4,077,981 — flagged in the answer as an action-level count (task orders and modifications included), “context only,” not a count of distinct prime contracts.
Note the shape of the response. The agent did not just dump an API field; it named what “awarded” means in USAspending (obligated dollars, fiscal year, contracts only — IDVs, grants, direct payments and loans excluded) before quoting the number.
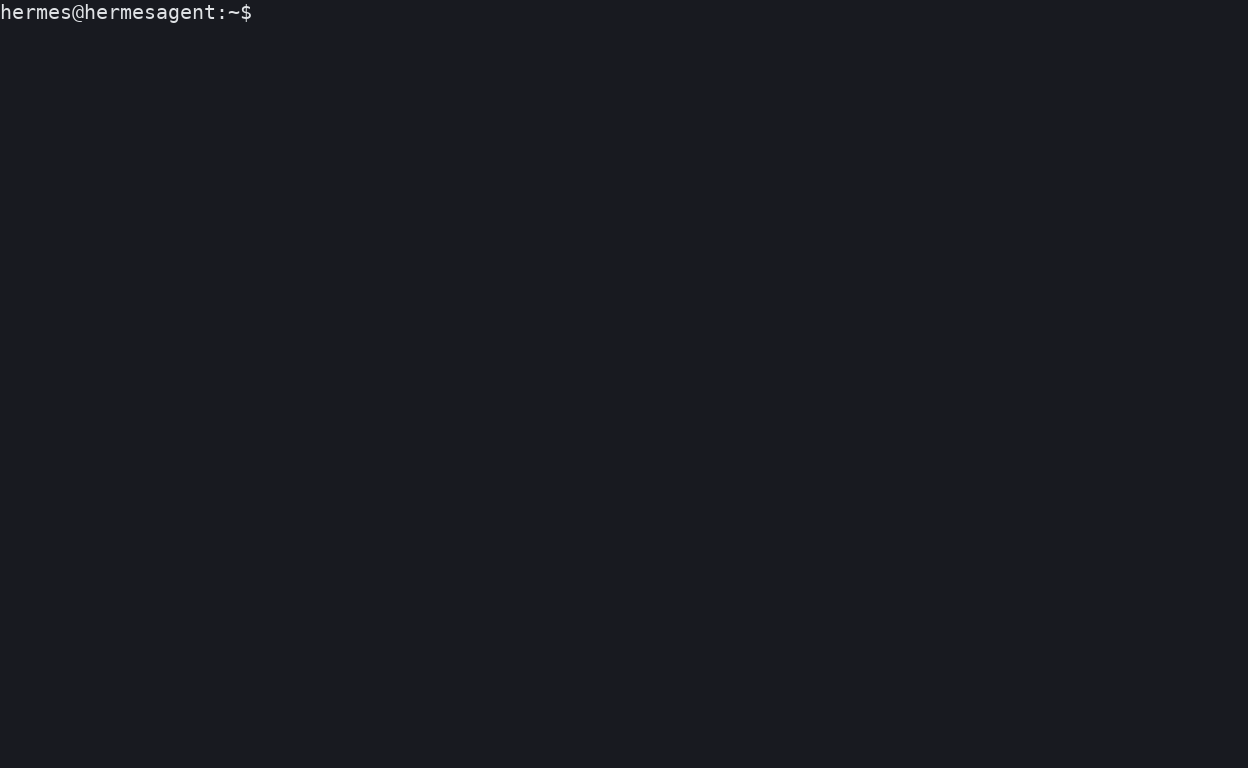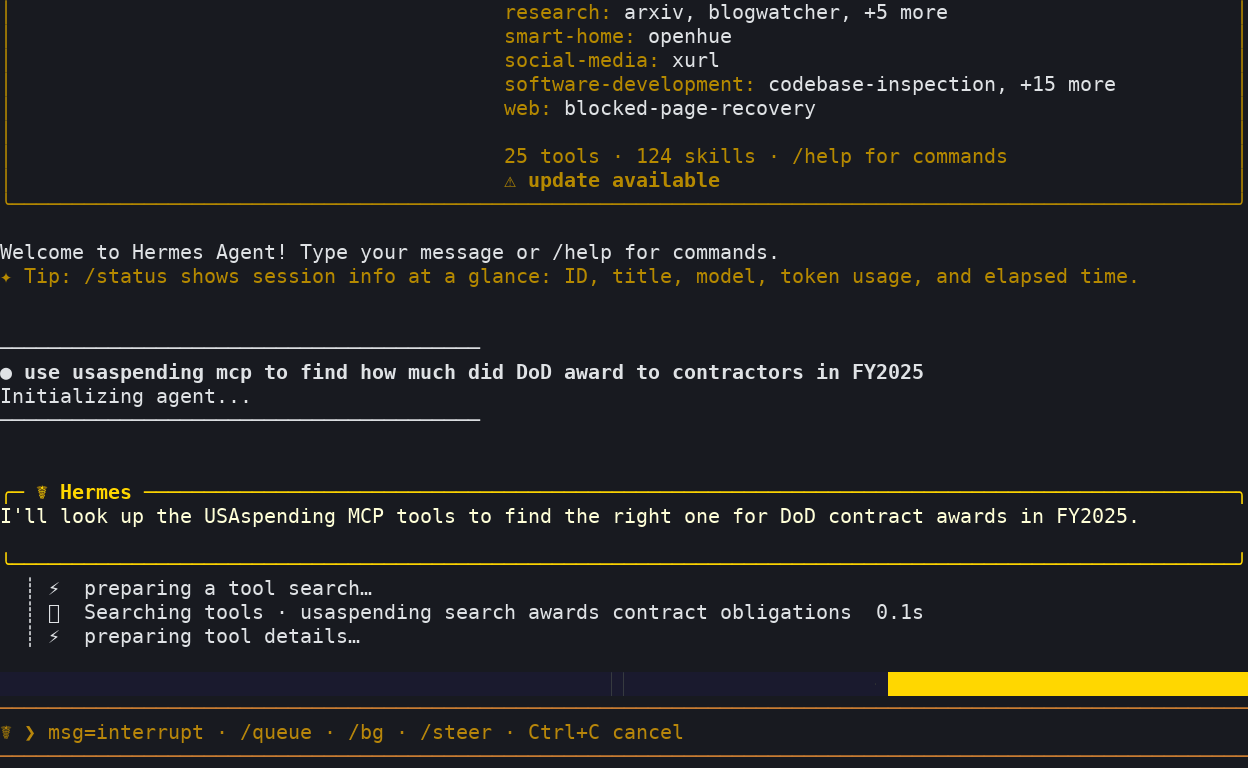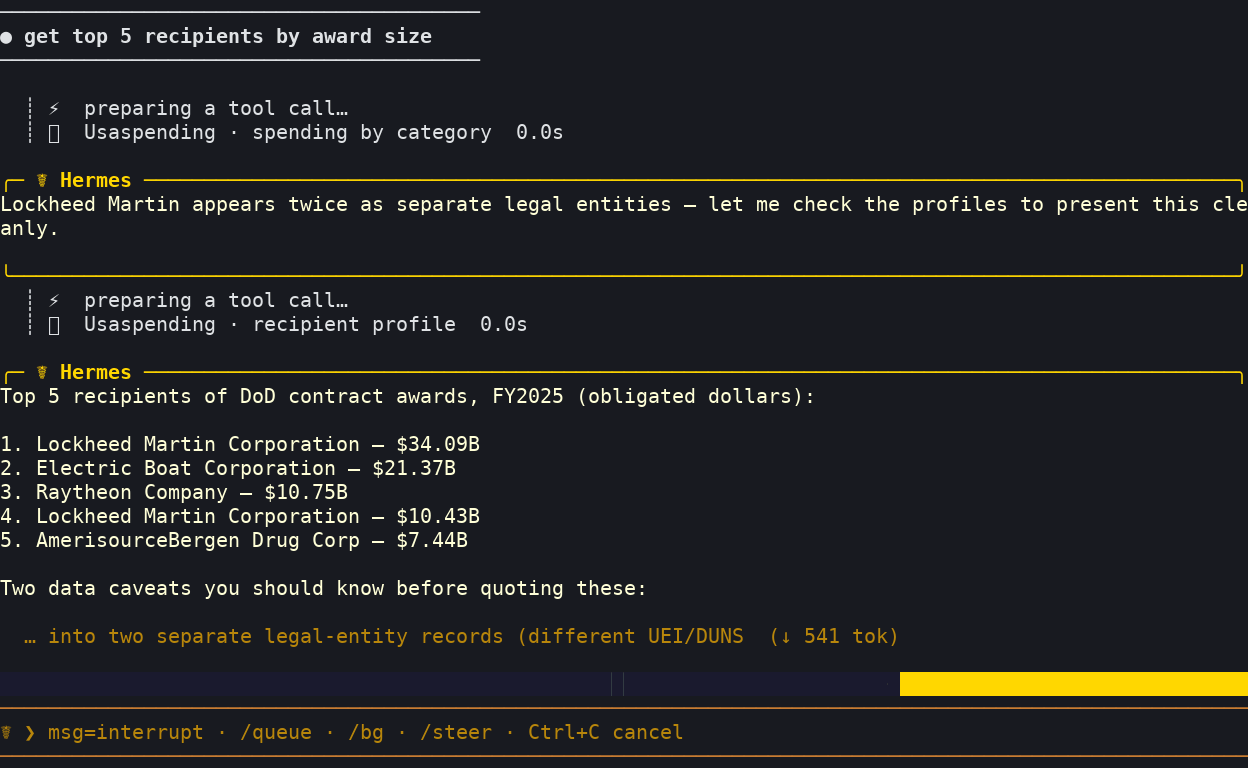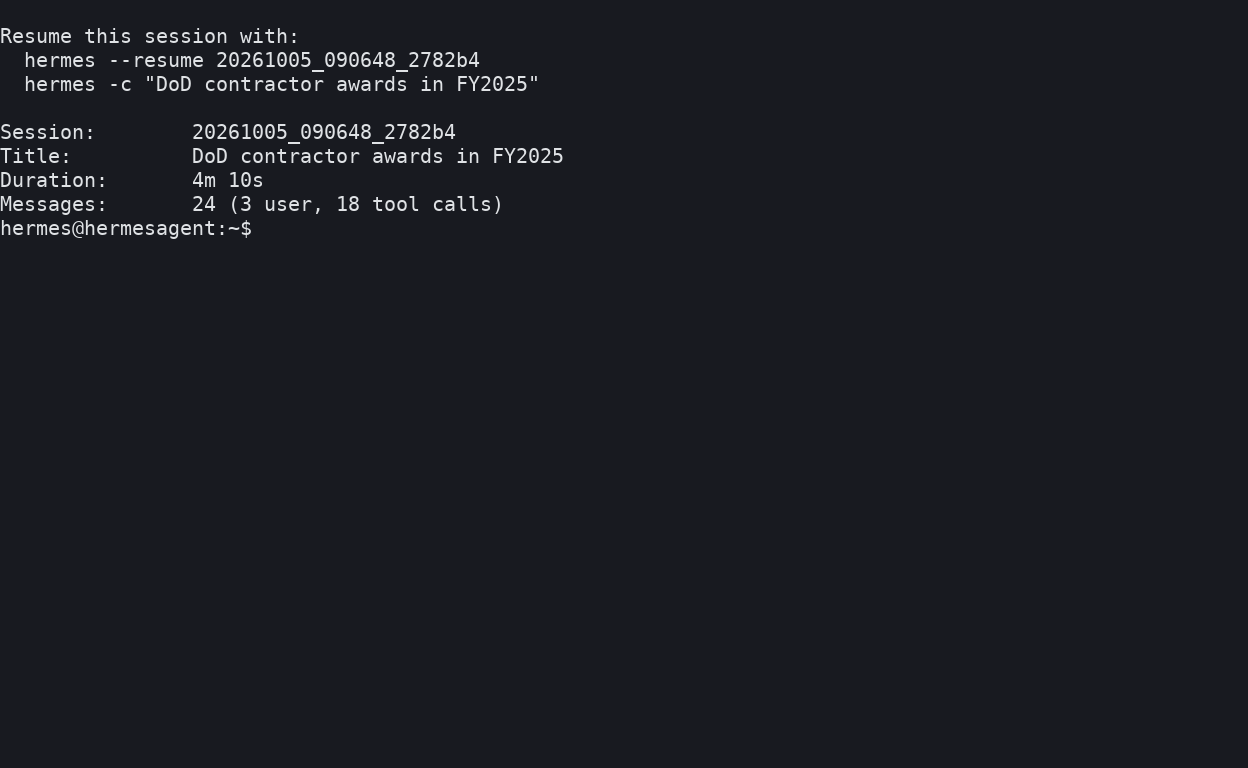
Question 2: “get top 5 recipients by award size.” spending by category again, grouped by recipient:
- Lockheed Martin Corporation — $34.09B
- Electric Boat Corporation — $21.37B
- Raytheon Company — $10.75B
- Lockheed Martin Corporation — $10.43B
- AmerisourceBergen Drug Corp — $7.44B
Lockheed appears twice — two legal-entity records with different UEIs. This is the moment the session earns its keep: the agent does not present the list and hope the reader notices. It pulls both profiles, plus the parent record, and reports that both entities trace to the same parent — Lockheed Martin Corporation, parent UEI JSQTW5L2SSM1 — for a consolidated FY2025 DoD total of ~$44.5B. It adds the other one for free: Electric Boat is a General Dynamics division, so GD’s true footprint is larger than its single line.
Question 3: “Pull the profile of Lockheed Martin.” recipient profile on both entities. The structure comes back as USAspending models it: a corporate umbrella parent — LOCKHEED MARTIN CORPORATION, parent UEI JSQTW5L2SSM1, DUNS 834951691 — with no financials of its own (totals live at the child-entity level), and two active contracting entities beneath it: Entity 1, Fort Worth, TX ($34.09B FY2025) and Entity 2, Grand Prairie, TX ($10.43B FY2025). Consolidated: ~$44.52B.
And the last two lines of that profile output in the recording are the ones I would frame and put on a slide:
The “lifetime / all-time” figures on the two entities ($13.48B and $14.40B) look lower than the single-year FY2025 DoD totals ($34B and $10.4B). That’s a data artifact — the total_transaction_amount field on the profile endpoint doesn’t reliably reconcile to the award-level rollup. For client-facing work, I’d rely on the award-level numbers.
A weaker pipeline would have printed the profile totals and let a client notice the inconsistency in a deliverable. This one noticed it during the call, said so in the answer, and recommended which number to trust. That is the whole argument for the layer: the protocol is boring, but a layer that has been run against the real thing knows what “looks wrong” looks like.
The GIF is that session converted frame-by-frame. The original asciinema .cast can be embedded with playback controls (asciinema-player) if you want readers to step through it themselves.
You could do this without MCP — here is what you lose
This is the honest section, and the answer is: yes, mostly you can. Put the USAspending API docs in the prompt and a capable agent will write a throwaway script, query the API, and answer your question. For one question on one machine, that is genuinely fine, and you should not build infrastructure for it.
What you lose, in order of how much it hurt us:
- The docs are wrong in exactly the places that matter. USAspending’s API churned in early 2026, and parts of the documentation describe behavior that no longer works. The transactions endpoint, for example, returns a 400 if you omit
award_type_codes— documented as optional. Pagination is 10 rows per page, not 20. Apiidfilter only works when paired with a recipient name. An agent working from the docs will confidently hit the documented behavior, get a 400, and then spend its turns improvising — sometimes “fixing” the query in a way that silently changes what it is measuring. Our tool docstrings encode what we verified live, and our test suite re-checks it. - It is re-derived from scratch every session. The workaround you wrote in March is not in the agent’s head in April. The MCP server is the workaround, persisted and versioned.
- Maintenance scatters. The API changes next year. With the server, we patch one file and every client — on every machine, in every harness — gets the fix. Without it, you hunt down every script and every prompt.
- Consistency and auditability. The same named tools, the same call shape, the same result schema in every harness. For client work, “here is exactly what the agent asked for, and here is the raw response” is a defensible record. A throwaway script’s request is not.
One question: prompt and docs are enough. Repeated questions, across four harnesses, with a data source that changes under you: this.
One file, four clients
Because the server is stdio and self-contained, “deploying” it in a harness is a registration line. Codex:
[mcp_servers.usaspending]
command = "uv"
args = ["run", "--with", "fastmcp>=3", "python", "/path/to/usaspending_mcp.py"]
startup_timeout_sec = 30
Claude Code is a one-liner:
claude mcp add --scope user usaspending -- uv run --with 'fastmcp>=3' python /path/to/usaspending_mcp.py
The one gotcha worth a paragraph: the first-launch cold start. On a clean machine, that uv run downloads the Python environment and dependencies inside the harness’s connection timeout. The server is not broken; it is downloading. Symptoms: Claude Code hangs at “starting server,” or reports a connection-closed error that does not reproduce later. Fix: run the command once by hand (let it finish, Ctrl-C), then register — the environment is cached, and the warm start is half a second.
Local versus online
We deliberately kept the server local. With stdio, each harness spawns its own process: no server to host, no URL to expose, no authentication to manage, and no way for anyone else on a network to reach it.
An MCP server can equally be served online: the same file running as a long-lived HTTP service at a URL, with any number of clients connecting over the network. The framework makes this a flag away, and we verified it works — pointed a client at the URL, got all 14 tools back, called one over HTTP. For this project we do not want it: one data shop, a handful of machines, and a service we would then have to keep alive, monitor, and authenticate. The rule of thumb we landed on: stdio until you have a concrete second consumer (another team, a phone, a client-facing app), then serve it and put it behind auth, because a public URL is reachable by anyone who finds it.
What it cannot do
- The key-gated LLM search endpoint is not exposed, so free-text “find me anything about X” queries are assembled from the structured tools, which is powerful but not a search engine.
- Federal records have gaps and lags: name variants, missing sub-awards, reporting delays. The server returns what the government reported; it does not fix what they did not.
- An MCP server gives an agent hands, not judgment. A bad filter in produces a confidently presented bad answer out. The docstrings make the common traps visible, but the person reviewing the result is still in the loop — which is how it should be for client work.
The pattern
Strip the federal part and the general shape is: a stable API, a lot of small quirks, and the same structured queries repeated by more than one consumer. That describes a client’s ERP, a data warehouse, an internal system with a login-free internal API. The one-file pattern — verified endpoints, quirks in the docstrings, slim projections, a live E2E suite — applies unchanged, and it is how we would wire an agent to a client’s proprietary data rather than a public one.
The full source and test suite for the USAspending server are in our repository. If you have an API your team keeps querying by hand, the gap between that and an agent that can query it on its own is usually a single file.